Customer Service Quality Assurance: What Gets Scored and Who Decides
Customer service quality assurance has five jobs, and software now does one: scoring. Here is what call center quality assurance still leaves to supervisors.
A supervisor who used to listen to a handful of recordings a week now opens a report where every contact has already been scored. So what’s left for people to do?
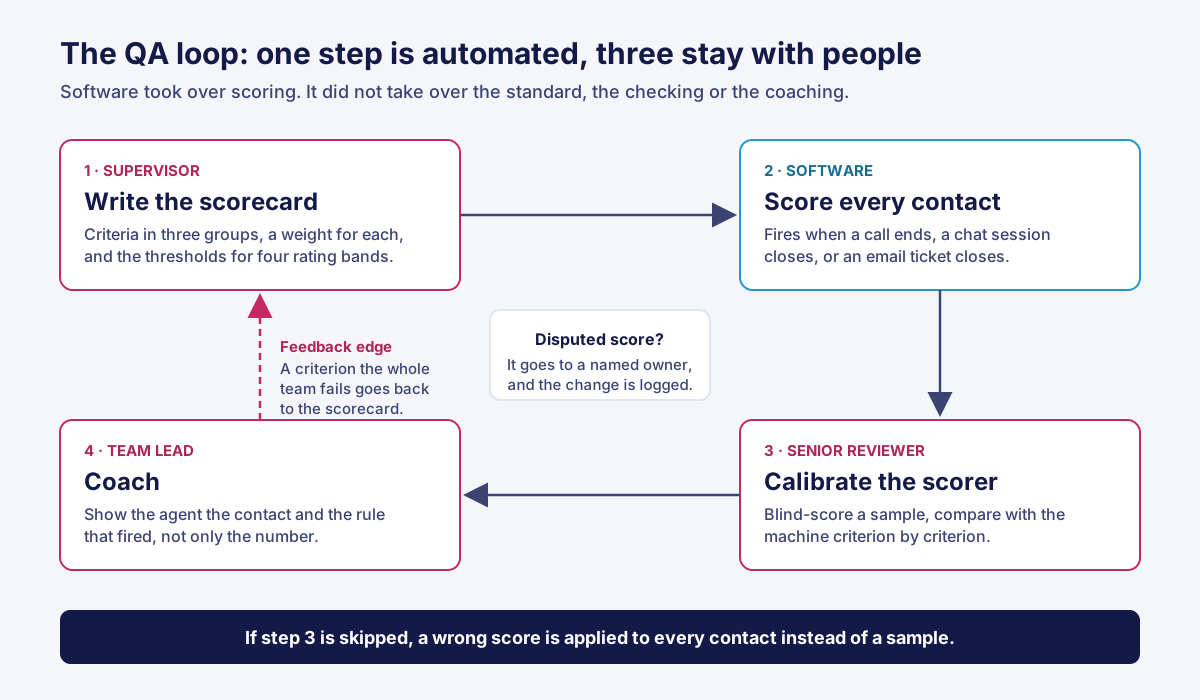
Customer service quality assurance checks support contacts against a written standard. It shows whether human agents followed the rules, where they need coaching, and whether a policy was broken. Software can do the scoring, but a supervisor still writes the standard, checks the scores, and uses the results to coach the team.
On this page
- TL;DR
- What it means in a support team
- What gets scored
- Calibrating the scorer
- Coaching
- QA scores and outcome metrics
- Manual, automated or hybrid
- Five checks and a starting checklist
- FAQ
TL;DR: customer service QA in one table
Customer service QA has five jobs. Software can assess every contact; assign a person to own each of the other four jobs so someone checks the results and follows up.
| Job | Who does it | How often | What happens if it’s skipped |
|---|---|---|---|
| Write the scorecard | Supervisor or QA lead | Once, then whenever the service standard changes | The machine applies a scorecard nobody chose |
| Score every contact | Software | When each call, chat or ticket ends | You’re back to sampling |
| Calibrate the scorer | A senior reviewer | On a schedule, and after every change to the criteria | Wrong scores get applied at full volume |
| Coach | Team lead | In regular one-on-ones | Nothing changes on the floor |
| Handle disputes | One named owner | As they come in | Agents stop trusting the number |
What quality assurance in customer service means
Quality assurance in customer service is a review of work after the contact ends. The reviewer compares what happened with a written standard and records whether the agent met it.
QA, QC and monitoring are three different jobs
ISO 9000:2015, the vocabulary standard behind ISO 9001, defines quality assurance as the “part of quality management focused on providing confidence that quality requirements will be fulfilled,” and quality control as the part “focused on fulfilling quality requirements.” QC makes one reply right, and QA tells you whether replies are right in general.
| When it happens | The question it answers | A support example | Who owns it | |
|---|---|---|---|---|
| QC | Before a reply is sent | Can this go out? | A pre-send filter blocks a message that contains a banned phrase or an outside link | Tooling, set up by a team lead |
| QA | After the contact ends | Was the standard followed? | A closed ticket is scored against written criteria | QA analyst or supervisor |
| Monitoring | While it’s happening | What’s going on right now? | A supervisor listens in on a live call | Supervisor |
That’s why quality control customer service tooling sits in the reply box, and QA sits in reporting. A pre-send filter is a word match, so it catches slips and people who didn’t know the rule. It won’t catch someone who splits a URL in half to get past it, which takes QA and permissions.
Call center quality assurance: what changes on a phone call
Call center quality assurance is the same job with one extra step: a call has to be transcribed before software can read it, so the transcript’s accuracy sits underneath every score. The familiar line “this call may be recorded for quality assurance” exists so that the recording can be reviewed afterward.
Recording rules differ by country and, in the US, by state. Some states require every party’s consent, and your agents are a party too. We cover whether the people being scored were told separately.
Who does call center QA now
For most teams, call center QA is still a role: the QA analyst. Before automated scoring, that analyst’s week was mostly listening. Now it splits three ways: keeping the scorecard current, auditing the machine’s scores, and preparing coaching material for team leads.
Credit unions, health plans and membership clubs run the same program and call it member service.
What gets scored: QA for customer service starts with a scorecard
A QA scorecard lists what good service should look like, with one criterion on each line. Each criterion gets a weight, which sets how much it contributes to the final total. Most support teams use three groups: resolution (was the problem solved), compliance (was there prohibited phrasing or an unauthorized promise), and product knowledge (did the answer match the knowledge base?). The weighted total is the contact’s QA score. A rating band turns that number into a category your team can use.
Criteria, weights and rating bands
Here’s one closed ticket scored on five items whose weights add up to 100.
| Item | Group | Weight | Rating (0–5) | Weighted points |
|---|---|---|---|---|
| The customer’s problem was actually solved | Resolution | 35 | 4 | 28 |
| Next step and owner were stated | Resolution | 15 | 5 | 15 |
| No prohibited phrasing | Compliance | 15 | 5 | 15 |
| No promise outside policy | Compliance | 10 | 5 | 10 |
| Answer matches the knowledge base article | Product knowledge | 25 | 3 | 15 |
| Total | 100 | 83 |
Each row is weight × rating ÷ 5, so this ticket scores 83. Which of your four bands 83 lands in depends on thresholds you choose. Set them once, for every queue.
A compliance failure can’t be averaged away. Had the agent promised a refund outside policy, the ticket would lose 10 points on weights alone and still get 73. Make compliance items auto-fail: miss one, and the contact fails whatever the total says.
Give the machine scorer something it can check in the conversation. “Shows empathy” leaves it to guess what you mean. “Acknowledges the delay before asking for the order number” names a specific action it can look for.
What counts as one unit: a single contact or the whole ticket
Decide whether each assessment should cover one phone call or the customer’s whole ticket. Much of the advice on scoring assumes the first option.
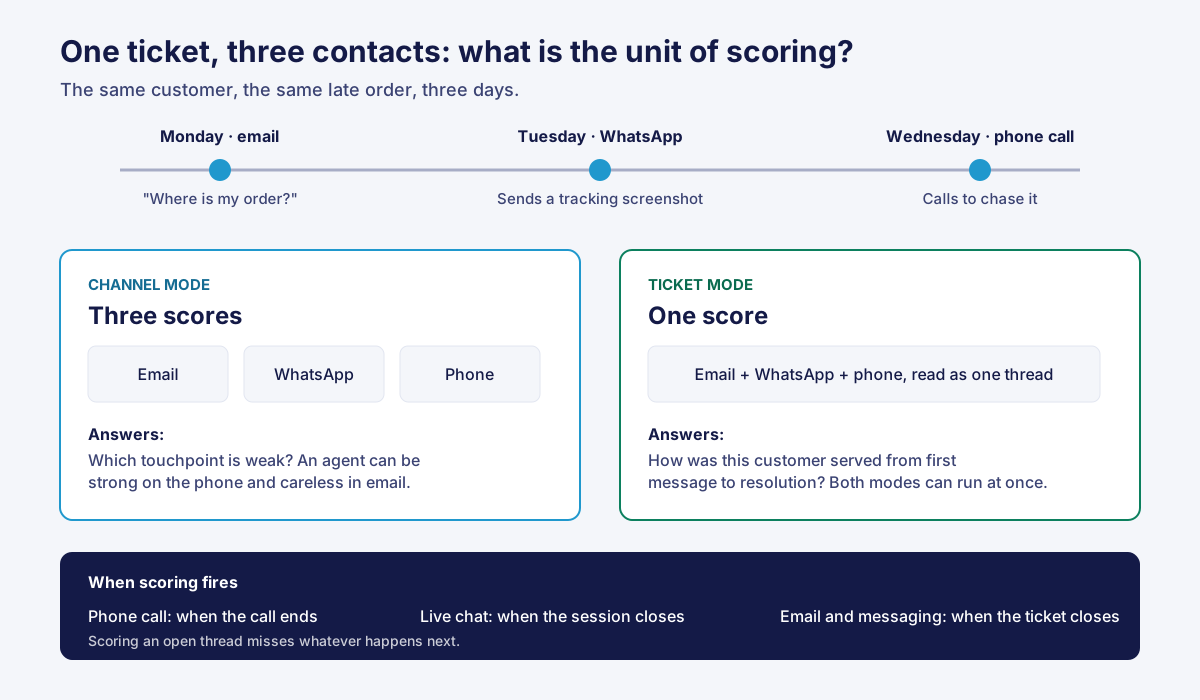
It matters as soon as a customer switches channels. Say someone emails on Monday about a late order, sends a WhatsApp screenshot of the tracking page on Tuesday, and phones on Wednesday to chase it.
- Channel mode gives three scores, one per contact, and shows which touchpoint is weak.
- Ticket mode gives one score for the whole thread, and shows how this customer was served from first message to resolution.
You can run both, but ticket mode only works if the three contacts land on one ticket. If they don’t yet, fix ticket triage first.
Timing follows from that: a phone call is scored when it ends, a live chat when the session closes, and email and messaging when the ticket closes, because an open thread isn’t finished.
Calibration: checking the scorer, human or machine
Scoring every contact solved the coverage problem, and we’ve written about why sampling four calls a month fails. It left open whether the scores are right. Wrong scores applied to every contact do more damage than wrong scores applied to a sample.
In one survey of 600 contact center professionals, nine in ten centers use AI to assess interactions (ScorebuddyCX, 2026). Only 14% said a person reviews every AI-generated evaluation, and almost half check sometimes, rarely or never. ScorebuddyCX sells QA software and hasn’t published its survey method, so treat the figures as a vendor’s.
Two kinds of calibration
Calibration checks whether scorers apply the same standard to the same call. Traditionally, several reviewers rate it, compare their decisions, and work through disagreements. With automation, you also compare a reviewer’s judgment with the machine’s result.
If two reviewers disagree, check whether the item’s wording is unclear or one reviewer interpreted it differently. If a reviewer and the machine disagree, check the prompt, the weight, and the reference article the machine used before correcting the cause.
To calibrate against a machine:
- Pull a sample from every rating band, because a random draw is mostly passes.
- Have a senior reviewer score each contact without seeing the machine’s number.
- Compare item by item, because matching totals can hide an auto-fail item that’s being scored wrong.
- Where the two disagree, decide who was right and fix the cause.
- Log every overturned score, with the item and the reason.
If the sample includes Spanish or German tickets, the blind reviewer has to work in that language, a staffing question we cover under multilingual call center services.
Measuring agreement
Percent agreement can make consistency look better than it is. Take one auto-fail item, marked pass or fail. Out of 50 contacts, the reviewer and the machine agree on 46, giving 92% agreement. Nearly every contact passes, though, so two scorers who simply passed everything would also agree most of the time.
Cohen’s kappa adjusts for the agreement you’d expect by chance. It helps you check whether the scorers agree beyond what the common pass rating would explain. For the same data it comes out at 0.46. The script below reproduces the number.
from collections import Counter

def cohen_kappa(human, machine):
    """Agreement between two raters on the same items, corrected for chance."""
    assert len(human) == len(machine) and human, "need two equal, non-empty lists"
    n = len(human)
    observed = sum(h == m for h, m in zip(human, machine)) / n
    h_counts, m_counts = Counter(human), Counter(machine)
    expected = sum(h_counts[k] * m_counts[k] for k in h_counts) / (n * n)
    if expected == 1:          # both raters gave every item the same label:
        return float("nan")    # kappa is undefined, so widen the sample
    return (observed - expected) / (1 - expected)

# One scorecard item, 50 contacts. P = pass, F = fail.
# Both fail 2, only the human fails 3, only the machine fails 1, both pass 44.
human   = ["F"] * 2 + ["F"] * 3 + ["P"] * 1 + ["P"] * 44
machine = ["F"] * 2 + ["P"] * 3 + ["F"] * 1 + ["P"] * 44

agree = sum(h == m for h, m in zip(human, machine)) / len(human)
print(f"percent agreement: {agree:.0%}")                      # 92%
print(f"cohen's kappa:     {cohen_kappa(human, machine):.2f}")  # 0.46

# Run it once per scorecard item, never on totals alone.
# On a small sample kappa swings a lot. Widen the sample before changing a prompt.
One widely cited table reads 0.60–0.79 as moderate agreement, 0.80–0.90 as strong, and above 0.90 as almost perfect (McHugh, 2012). By that table, 0.46 is weak. It was written for clinical research, where the bar is high, so use it as a starting point.
A low kappa on one item is useful data: it tells you which prompt to rewrite, and the next round tells you whether the rewrite worked.
Which scores a person always reviews
Reviewing all the machine’s scores would put you back where you started. Three kinds always get a person:
- Scores that feed a performance decision, such as pay, a warning or a promotion.
- Any contact that auto-failed.
- Anything an agent disputes.
Give those to one named owner, and put everything else on a schedule.
Coaching: turning a score into a changed call
Use the score to choose what to discuss in coaching. Call center quality improves when the agent understands which action to change on the next contact; the report helps you find that action.
Three report views are enough to start: an agent ranking shows who needs coaching, a breakdown by item shows what the whole team gets wrong, and a trend line shows whether last month’s coaching held.
Practitioners interviewed for a trade piece have agents score their own calls before the session (Call Centre Helper, 2026). Nerys Corfield of Injection Consulting said agents who do this “stop seeing QA as mysterious.” The item where the agent and the evaluator differ most becomes the topic.
In the session, show the contact and the rule that fired, because a bare number invites an argument about the number. Then check one thing before coaching anyone:
- One agent is low on an item. Coach that agent, and look at the trend next month.
- The whole team is low on it. Don’t coach 20 people on the same thing, because the process, the policy or the reference article is wrong. Fix that, and send the item back to whoever owns the scorecard.
Keep an action record for each coaching decision: the scorecard item, example contact, person responsible for the change, due date, follow-up sample and reviewer decision. Agree what evidence would close the action before assigning it. If the follow-up sample shows the same problem, record the next change and review it again.
HeroDash’s training workflow connects courses, knowledge tests, AI role-play, certification and QA feedback, with further training assigned for weak areas. If your program uses that workflow, keep the training result and the later contact review in the action record. When the issue is an incomplete transfer, use the escalation handoff checks to establish which step failed before choosing the coaching task.
QA scores and outcome metrics answer different questions
A QA score tells you whether the agent followed the standard. Customer satisfaction (CSAT), Net Promoter Score (NPS) and first contact resolution (FCR) measure aspects of the customer’s experience. Customer experience quality assurance needs both: following the rules doesn’t by itself show that the customer got a useful result.
| Metric | What it counts | What it tells you | What it can’t tell you |
|---|---|---|---|
| QA score | Items met on one contact | Whether the standard was followed | Whether the customer cared about that standard |
| CSAT | Survey answers after a contact | How this customer felt about this contact | Which sentence caused it |
| NPS | Likelihood to recommend, asked occasionally | How customers feel about the company | Anything about a single agent |
| FCR | Contacts resolved without a repeat | Whether problems are being solved the first time | Why the unsolved ones weren’t |
| Service level | Calls answered inside a time threshold | How fast you pick up | Anything about what was said |
When the two kinds disagree, the disagreement is the finding. High QA scores with low CSAT mean you’re scoring things customers don’t care about, so change the standard. Low QA scores with high CSAT mean an item is too strict or no longer relevant.
Check denominators before comparing KPIs across teams or vendors: one definition of service level divides by calls answered, and another by calls offered, which includes abandoned ones.
Manual, automated or hybrid: three ways to run service quality assurance
There are three ways to run service quality assurance, and they differ mainly in who answers for the scores.
| Manual sampling | Machine only | Machine scores, supervisor calibrates | |
|---|---|---|---|
| Who writes the scorecard | QA analyst | Often the vendor’s default template | Your supervisor |
| Who answers for the scores | The reviewer who gave them | Nobody | A named owner |
| Fits | A small team with low volume | Rarely anyone for long | Teams with too much volume to read by hand |
Manual sampling leaves some contacts unreviewed. Machine-only scoring covers the contacts, but nobody is responsible for checking whether the scores are right. The hybrid model keeps that check and requires supervisor time to do it.
Where Callnovo.ai fits
Callnovo.ai (human agents working in 65+ languages on its own platform, HeroDash) is built for the third model. HeroDash’s AI QA fires automatically when a service contact ends: a phone call when the call ends, a live chat when the session closes, and email, WhatsApp, Facebook, Instagram, SMS and eBay messages when their ticket closes. Channel mode and ticket mode can be on at once.
The scorecard belongs to the customer. Its items sit in three groups (general, compliance and product knowledge), and each gets a weight, a rating range and a plain-language prompt. Product-knowledge items can be checked against a linked knowledge base. Four rating bands apply to every rule, and the customer sets the thresholds. Reports come in four layouts: overview, agent ranking, trend and distribution by item. The product is HeroScore, and it runs on HeroDash.
It doesn’t write your scorecard or settle a disputed score. It only scores contacts handled on HeroDash, so work your team does in another tool isn’t covered. It’s also a paid add-on: our published pricing lists Omnichannel AI QA at US$30 per agent per month, with no extra charge when you staff with Callnovo.ai’s human agents.
A medical device manufacturer selling in more than 120 countries reviewed its after-sales calls by hand and reached 5% of them. One year after the account moved to Callnovo.ai’s multilingual support teams on HeroDash, every call on it was reviewed. The case study has the rest.
When you don’t need to buy anything
If one supervisor can read every ticket your team closes in a week, you don’t need QA software, ours included. Write the scorecard, apply it by hand, and spend the money somewhere else.
If your agents work in your own helpdesk and you want QA inside it, a dedicated QA platform will integrate more deeply than we do. If you’re choosing a tool, read what to ask before buying QA software.
When a support QA program isn’t working: five checks and a starting checklist
A support QA program that works produces a spread of scores, a log of overturned ones, and now and then a process change. If yours produces only a dashboard, start here.
| Symptom | Check this first |
|---|---|
| Every agent lands in the top band | Whether your criteria can tell good work from average work |
| Scores are high and complaints haven’t dropped | Whether the items are things customers care about |
| A reviewer and the machine disagree about the same contact | Agreement on each item, one at a time |
| Agents reject their scores | Whether they were shown the rule, and whether a dispute route exists |
| The whole team is low on one item | The process or the reference article behind it |
Three questions to ask yourself:
- Who overturned one of the machine’s scores last month, and where is it written down? If nobody did, either the machine is perfect or nobody is checking.
- Can an agent see the rule behind yesterday’s number? If not, the number is a verdict, and people argue with verdicts.
- When did a QA finding last change a process? If you can’t name one, the program is measuring agents and nothing else.
A checklist to start from:
- Write the criteria in three groups and give each a weight.
- Set the thresholds for your rating bands and mark which compliance items auto-fail.
- Decide whether you’re scoring each contact, each ticket, or both.
- Pull a first sample from every band and have a senior reviewer score it blind.
- Name the owner of disputed scores, tell agents how to raise one, and date the first calibration session.
Customer service quality assurance didn’t get smaller when software started scoring. The listening went away, but the judgment about what good service is, and whether the scorer has it right, is still a supervisor’s work.
References
- ISO 9000:2015, Quality management systems — Fundamentals and vocabulary, terms and definitions. https://www.iso.org/standard/45481.html
- McHugh ML. Interrater reliability: the kappa statistic. Biochemia Medica 2012;22(3):276–282. https://pmc.ncbi.nlm.nih.gov/articles/PMC3900052/
- Derek Corcoran (Scorebuddy), citing ScorebuddyCX’s AI Reality Check (600 respondents; method not published). Call Centre Helper, 2 October 2026. https://www.callcentrehelper.com/how-often-review-ai-qa-scores-277808.htm
- Robyn Coppell, How to Communicate Your QA Framework Clearly. Call Centre Helper, 6 October 2026. https://www.callcentrehelper.com/communicate-qa-framework-clearly-274007.htm
- Callnovo.ai, medical device after-sales case study, 2026. https://callnovo.ai/blog/case-study-medical-device-maker-30-language-after-sales-support/
- HeroDash, AI QA product release (in Chinese), July 2026.
Questions buyers ask
- What is QA for customer service?
- QA for customer service is the review of finished support contacts against a written standard. It confirms that human agents followed that standard, shows what to coach, and catches policy violations. Every call, chat and ticket can now be scored by software, but writing the standard, checking the machine's scores and coaching remain a supervisor's work.
- What is the difference between quality assurance and quality control in customer service?
- ISO 9000:2015 defines quality assurance as providing confidence that quality requirements will be fulfilled, and QC as fulfilling them. In a support team, QC stops a bad reply before it's sent, for example with a pre-send filter. QA reviews what was sent and reports whether the standard is being met.
- What does QA do in a call center?
- A call center QA analyst keeps the scorecard current, audits scores, and prepares coaching material for team leads. Before scoring was automated, most of the week went to listening to recorded calls. Now the listening is limited to calibration samples, failed compliance checks and disputed scores.
- How many tickets should you review?
- Let software score all of them, and have a person review three kinds: scores that feed pay or performance decisions, failed compliance items, and disputed scores. Add a calibration sample drawn from every rating band, large enough that the agreement figure holds steady between rounds.
- Can AI replace human reviewers in customer service QA?
- No. AI replaces the listening. It doesn't decide what good service is, and it can't tell you whether its own scores are right. In a 2026 ScorebuddyCX survey of 600 contact center professionals, only 14% said a person reviews every AI-generated evaluation. Someone still has to own the standard.